Data Engineering & Analytics: Engineered for Sub-Second Clarity
Turn scattered operational records into one dependable view: automated pipelines, clean data models and fast dashboards showing the numbers that drive decisions — with an owner for every metric.
Best for growing businesses in India, the USA, UK, Australia and Canada where you have data in three or more tools, spend hours copying into spreadsheets, and need one dependable view with metrics everyone agrees on. Fixed-price project per dashboard suite; ongoing pipeline monitoring optional.
Executive Brief
Strategic Context & Engineering Purpose
How our dashboards project engagements de-risk operational transitions and produce enduring software assets.
Operational Challenge
Mid-market operating companies and high-growth technology enterprises routinely find themselves paralyzed by fractured, conflicting business metrics. Commercial data lives trapped across ten to twenty disparate SaaS silos—including Stripe, Salesforce, HubSpot, Shopify, Google Ads, and custom PostgreSQL production databases. Executive leadership and department directors waste dozens of weekly operational hours manually copying and pasting numbers into fragile, error-prone Google Sheets and Excel workbooks that break whenever formulas change. Conflicting metric definitions create heated internal debates over fundamental business facts—such as actual customer acquisition cost (CAC), gross margin retention, and inventory turnover—destroying executive trust and delaying high-stakes strategic capital allocation.
Architectural Approach
We design and deploy modern, unified data engineering platforms rooted in automated ELT extraction (Airbyte, Fivetran), dimensional cloud data warehousing (Snowflake, BigQuery, ClickHouse), and modular transformation pipelines managed via dbt (data build tool). Our data architects establish a single, governed semantic layer that establishes mathematically unambiguous metric definitions across the entire enterprise. Every raw data ingestion pipeline is guarded by automated schema validation tests (Great Expectations) and anomaly detection alerts that catch corrupted records before they pollute downstream reporting. We deliver blazing-fast executive BI dashboards (using Metabase, Superset, or Tableau) with pre-aggregated data marts that render multi-million-row operational queries in under five hundred milliseconds.
Measured Economic Impact
Unifying corporate data into a centralized, automated analytical warehouse completely eliminates reporting ambiguity and transforms organizational decision-making velocity. Executive teams transition from waiting weeks for stale end-of-month financial spreadsheets to viewing live, daily automated operational dashboards that reflect ground-truth reality. Administrative data reconciliation overhead drops by over eighty-five percent across finance, marketing, and operations departments, freeing key staff to focus on strategic execution rather than manual reporting. Furthermore, sub-second query performance and self-serve semantic models allow business operators to independently drill down into unit economics, cohort retention, and churn indicators without filing engineering tickets.
Governance & IP Custody
We enforce uncompromising data security, radical engineering transparency, and permanent intellectual property ownership across every data engagement. All dbt models, SQL transformation queries, Airflow/Prefect orchestration DAGs, and warehouse schemas are version-controlled directly inside your corporate GitHub or GitLab repository. All infrastructure is deployed strictly within your corporate cloud accounts (AWS, GCP, or Snowflake) with role-based access controls and encrypted VPC private links—we never route your sensitive business records through agency servers. Upon delivery, we provide comprehensive data dictionaries, metric lineage graphs, and recorded administrative walkthroughs, guaranteeing total autonomy for your internal team.
Engineering Architecture
Core Technical Blueprints & Subsystems
Every system is modularized into isolated subsystems with strict interface contracts and automated testing.
Automated ELT Data Pipelines & Ingestion Engine
Resilient connectors, incremental CDC extraction, and schema drift handling
Manually downloading CSV reports and running brittle cron scripts creates severe data latency and frequent silent pipeline failures. We engineer robust, automated ELT extraction pipelines using Airbyte or custom Python runners that interface with cloud APIs, webhooks, and production transactional databases via Change Data Capture (CDC). Ingestion jobs utilize incremental extraction with watermark timestamp tracking, syncing only modified records to minimize API rate limits and network bandwidth. Webhook ingestion endpoints are backed by Kafka or Redis buffers that absorb sudden data spikes during marketing campaigns, ensuring zero record loss during downstream warehouse maintenance windows.
Code & Schema Deliverables:
- Automated incremental ELT pipeline connecting SaaS platforms, payment gateways, and SQL databases
- Change Data Capture (CDC) replication from production PostgreSQL/MySQL with zero query performance impact
- Durable webhook ingestion buffer utilizing Kafka or Redis for high-throughput event streaming
- Automated schema drift detection that quarantines altered payloads without halting pipeline execution
Failure Modes Prevented:
- ✕Silent data pipeline failures where broken SaaS API updates go unnoticed for weeks until reports fail
- ✕Production transactional database slowdowns caused by heavy, un-indexed analytical reporting queries
- ✕Duplicate record ingestion caused by unhandled network disconnects during large historical data syncs
- ✕API rate limit bans triggered by un-throttled, un-coordinated third-party API polling jobs
Tech Stack
Dimensional Data Warehouse & dbt Transformation Engine
Star-schema dimensional modeling, incremental dbt models, and lineage graphs
Raw operational data is messy, normalized for transactional writes rather than analytical reads, and full of inconsistent naming conventions. We build clean, dimensional data warehouses in BigQuery, Snowflake, or ClickHouse modeled into Medallion architecture (Bronze raw, Silver cleaned, Gold business marts). Our transformation logic is authored in modular, version-controlled dbt (data build tool) utilizing star-schema dimensional modeling (Fact and Dimension tables). Heavy transformation models are configured as incremental materializations that update only newly ingested records, slashing warehouse compute credits by up to seventy percent while maintaining real-time freshness.
Code & Schema Deliverables:
- Modular dbt project with structured Bronze, Silver, and Gold dimensional star-schema models
- Incremental materialization configurations optimizing warehouse query execution and cloud credit spend
- Comprehensive metric documentation and interactive dependency lineage graphs generated in dbt docs
- Automated data retention and cold storage tiering policies minimizing long-term warehouse storage fees
Failure Modes Prevented:
- ✕Exploding monthly cloud warehouse compute bills caused by executing full-table scans on every query
- ✕Conflicting metric definitions between departments resulting from isolated, uncoordinated SQL queries
- ✕Circular table dependencies and broken transformation DAGs caused by undocumented SQL edits
- ✕Loss of historical dimension state prevented via automated Type 2 Slowly Changing Dimensions (SCD2)
Tech Stack
Semantic Metrics Layer & Sub-Second Executive BI Dashboards
Single source of truth metrics, pre-aggregated OLAP cubes, and interactive drill-downs
Dashboards that take twenty seconds to load are abandoned by executive leadership. We architect high-performance business intelligence platforms utilizing Metabase, Apache Superset, or Cube.js backed by pre-aggregated OLAP tables and materialized views. We implement a centralized semantic metrics layer where core KPIs—such as Customer Acquisition Cost (CAC), Net Revenue Retention (NRR), Gross Margin, and Days Sales Outstanding (DSO)—are codified once in code and reused consistently across all executive, departmental, and customer-facing reports. Dashboards load in under five hundred milliseconds globally, featuring intuitive filtering, date cohort comparisons, and automated scheduled PDF/Slack delivery.
Code & Schema Deliverables:
- Centralized semantic layer defining core organizational KPIs with unified mathematical formulas
- Production executive BI dashboard suite covering Financials, Marketing, Operations, and Customer Retention
- Pre-aggregated data cubes and materialized caching layers guaranteeing sub-500ms dashboard render latency
- Automated daily and weekly metric summary digests dispatched directly to executive Slack channels or inboxes
Failure Modes Prevented:
- ✕Slow, unresponsive dashboards that cause executive leaders to abandon data platforms and revert to spreadsheets
- ✕Metric divergence where marketing, sales, and accounting report conflicting revenue and conversion figures
- ✕Unauthorized staff viewing sensitive executive payroll or profitability data due to missing dashboard RBAC
- ✕Dashboard outages caused by direct queries locking analytical database tables during peak business hours
Tech Stack
Data Quality Assurance, Anomaly Detection & Schema Testing
Continuous Great Expectations tests, freshness alerts, and automated data contracts
Bad data is worse than no data. When an upstream checkout provider alters a webhook field name or a sales rep enters a typo in a CRM deal value, unvalidated pipelines propagate erroneous figures directly into financial board reports. We implement continuous data quality assurance utilizing Great Expectations and Soda Core integrated directly into the ELT execution DAG. Every data load is automatically verified for null value thresholds, uniqueness constraints, acceptable numeric ranges, and referential integrity. If an anomaly is detected, the flawed data batch is automatically quarantined in a staging error table and on-call engineers are alerted immediately, preventing corrupted data from contaminating downstream executive marts.
Code & Schema Deliverables:
- Automated data quality test suite in Great Expectations validating schema, types, and value bounds
- Real-time pipeline freshness and volume anomaly alerting integrated into PagerDuty and Slack
- Quarantine table architecture capturing malformed or invalid records for manual inspection
- Formal data contract specifications agreed upon between software engineering and data teams
Failure Modes Prevented:
- ✕Corrupted financial reports presented to board members or investors due to undetected pipeline errors
- ✕Silent null data injection caused by upstream SaaS vendors altering JSON payload structures without notice
- ✕Duplicate transaction counting resulting in artificial revenue inflation and skewed margin analysis
- ✕Hours of manual debugging required to locate which specific ingestion batch introduced a calculation error
Tech Stack
Engineering Governance
Engineering Standards, QA & Security Protocols
Rigorous development disciplines that protect your code quality, deployment velocity, and infrastructure security.
Idempotent Pipeline Execution & Atomic Upserts
Data ReliabilityAll data ingestion and transformation jobs are engineered to be strictly idempotent. Rerunning a pipeline for a historical date range never duplicates records or corrupts aggregations. Writes utilize atomic database upserts (MERGE statements) wrapped in transactional boundaries.
Tooling & Rails
Semantic Layer Single Source of Truth & Versioning
Data GovernanceAll organizational metrics are defined declaratively in code within a version-controlled semantic layer. Formulas include explicit SQL filters, dimension relationships, and descriptive metadata, completely eliminating divergent spreadsheet calculations.
Tooling & Rails
Automated Data Quality Testing & Schema Drift Traps
Quality AssuranceEvery pipeline execution triggers automated Great Expectations and dbt test suites verifying primary key uniqueness, foreign key integrity, and column value distributions. Any test failure halts downstream mart building and dispatches high-priority Slack alerts.
Tooling & Rails
Sub-500ms P95 Analytical Query Performance
BI PerformanceDashboards query pre-aggregated summary tables and materialized views rather than raw transactional logs. Database queries utilize column-store compression, partition pruning, and cluster keys to ensure 95% of executive dashboard queries resolve in under 500ms.
Tooling & Rails
Production Case Evidence
Detailed Architecture Problem-Solution Blueprints
Real-world engineering case blueprints detailing baseline bottlenecks, technical intervention, and verified production metrics.
Operational Bottleneck & Root Cause
The executive team relied on four conflicting spreadsheets to track daily revenue and ad spend, discovering three weeks late that a major ad campaign was operating at a severe loss.
Root Cause: Data was siloed in Shopify, Amazon Seller Central, Meta Ads, and TikTok Ads, with no centralized data warehouse or automated attribution modeling.
Engineered Architecture
Implemented an automated ELT pipeline via Airbyte into BigQuery, modeled via dbt with automated blended ROAS attribution, and visualized in Metabase.
Measured Result
Eliminated 25 weekly hours of manual spreadsheet compilation; identified and cut $60K in unprofitable ad campaigns within the first two weeks.
Operational Bottleneck & Root Cause
Preparing for a Series B fundraise required three finance analysts working 70-hour weeks for a month to calculate historical cohort churn, expansion revenue, and Net Retention.
Root Cause: Subscription billing events were scattered across Stripe, manual Salesforce enterprise contract overrides, and PostgreSQL application product logs.
Engineered Architecture
Built a centralized subscription data mart in Snowflake using dbt, modeling daily recurring revenue (MRR/ARR) watermarks, cohort retention, and customer health scores.
Measured Result
Reduced board reporting preparation time from 30 days to 15 seconds with one-click automated dashboards; successfully closed $24M Series B round.
Operational Bottleneck & Root Cause
Sales reps had zero visibility into real-time branch inventory levels, resulting in frequent customer backorders and expensive emergency air freight shipments.
Root Cause: Legacy AS400 warehouse mainframe data was extracted via manual weekly batch dumps that failed to capture intra-week order movements and returns.
Engineered Architecture
Engineered a real-time CDC pipeline streaming inventory movements into ClickHouse with automated low-stock threshold alerting in Microsoft Teams.
Measured Result
Emergency expedited air freight expenses dropped by 74%; order fulfillment backorder rates decreased from 14% to under 1.5%.
Operational Bottleneck & Root Cause
Corporate leadership could not compare franchisee profitability because 120 franchise locations used different accounting categories and job tracking software.
Root Cause: Unstandardized chart of accounts, inconsistent job status nomenclature, and manual quarterly franchise financial self-reporting.
Engineered Architecture
Built an automated data normalization pipeline standardizing chart of accounts across all franchisees into a unified star-schema benchmarking portal.
Measured Result
One hundred percent on-time franchise royalty reconciliation; identified top quartile operational playbooks that lifted bottom-quartile franchise margins by 18%.
Sprint Delivery Cadence
Phased Sprint Roadmap & Quality Gates
Predictable milestone delivery with working software demoed every week in your repository.
Phase 01: Source System Audit, KPI Blueprint & Warehouse Architecture
Source data mapping, metric definition alignment, and cloud warehouse provisioning
Deliverables:
- Comprehensive source system audit cataloging all APIs, databases, tables, and credentials
- Executive KPI Blueprint document establishing standardized mathematical formulas for all metrics
- Cloud data warehouse landing zone setup on Snowflake, BigQuery, or ClickHouse with secure VPC links
- Automated ELT extraction pipeline setup for high-priority transactional and payment data sources
Gate Criteria
Approval of KPI formulas and verified raw data ingestion flowing into Bronze warehouse staging.
Phase 02: Dimensional Modeling, dbt Transformations & Lineage
Star-schema modeling, dbt transformation authoring, and automated testing
Deliverables:
- Complete dbt project authoring Silver cleaned models and Gold dimensional Fact/Dimension tables
- Automated incremental materializations optimizing query performance and warehouse compute credit spend
- Data quality test suite implementation using Great Expectations verifying primary and foreign keys
- Interactive data lineage documentation and metric dictionary deployed to internal documentation
Gate Criteria
Successful dbt run and test passing 100% of data quality checks on staging environment.
Phase 03: Executive BI Dashboard Engineering & Semantic Layer
Semantic layer configuration, BI dashboard building, and sub-second query tuning
Deliverables:
- Centralized semantic metrics layer deployment ensuring identical calculation logic across tools
- Executive BI dashboard suite covering Financials, Marketing Attribution, and Operational Velocity
- Pre-aggregated data cubes and materialized caching layers guaranteeing sub-500ms query latency
- Automated daily metric digest webhooks delivering KPI snapshots to executive Slack or Teams channels
Gate Criteria
Sub-500ms dashboard render latency verified across all executive views and historical numbers reconciled.
Phase 04: Data Quality Automation, Staff Training & Full Handover
Freshness alerting, access governance, operational documentation, and staff walkthrough
Deliverables:
- Automated pipeline freshness and volume anomaly alerting configured in PagerDuty or Slack
- Role-based access control (RBAC) implementation restricting sensitive payroll and margin views
- Recorded staff training workshop demonstrating how to build custom queries and explore self-serve data
- Comprehensive data dictionary, repository code transfer, and complete operational handover
Gate Criteria
Zero reconciliation discrepancies against ground-truth finance records and full IP sign-off.
Financial Transparency
Total Cost of Ownership & Risk Mitigation
Understand the core technical variables that dictate development investment and long-term operating costs.
Unified Warehouse Intelligence vs Fragmented Spreadsheet Waste
TCO VariablePrimary Cost Driver
Organizations spend hundreds of hours every month manually compiling, reconciling, and fixing broken spreadsheet reports.
Risk Without Proper Architecture
Executive leaders make multi-million-dollar decisions based on outdated or mathematically flawed manual spreadsheets, risking severe capital loss.
Our Engineering Mitigation
We automate 100% of data extraction and modeling into a governed warehouse, providing live, trusted numbers while eliminating manual busywork.
Incremental Warehouse Compute vs Runaway Cloud Query Credits
TCO VariablePrimary Cost Driver
Un-optimized analytical databases scanning millions of rows on every dashboard load incur skyrocketing monthly cloud credit charges.
Risk Without Proper Architecture
Naive SQL models that rebuild full tables continuously can cost thousands of dollars in unnecessary Snowflake or BigQuery compute bills.
Our Engineering Mitigation
We architect incremental dbt models and pre-aggregated OLAP tables that process only new records, slashing warehouse operating costs by 50-70%.
Automated Data Contracts vs Upstream Breakage Remediation
TCO VariablePrimary Cost Driver
Upstream third-party SaaS vendors and application developers frequently alter API schemas without prior notification to data teams.
Risk Without Proper Architecture
Undetected schema changes break executive dashboards right before board meetings, causing embarrassing credibility loss and emergency scrambles.
Our Engineering Mitigation
We implement Great Expectations automated quality gates and schema drift traps that quarantine bad records without crashing reporting pipelines.
Open-Source Portability vs Proprietary Analytics Vendor Lock-In
TCO VariablePrimary Cost Driver
Proprietary analytics SaaS platforms charge compounding per-seat fees while locking transformation logic inside proprietary black-box platforms.
Risk Without Proper Architecture
Your organization becomes held hostage by third-party analytics vendors, unable to export historical data or migrate to modern tools.
Our Engineering Mitigation
We build on open, industry-standard foundations (dbt, PostgreSQL/ClickHouse, Python, Metabase) with 100% code ownership in your Git repository.
Results
What This Service Delivers
Outcome 1
A dashboard that loads fast and stays current
Fast, automated dashboards that refresh daily — executives see accurate numbers without waiting for manual reports.
Outcome 2
One agreed definition for each core metric
A single agreed definition for every core metric, documented in a data dictionary your entire team can inspect.
Outcome 3
A data dictionary so anyone can verify numbers
Automated pipeline health alerts that catch broken feeds before bad data reaches decision-makers.
Fit Check
Is This Service Right for Your Business?
When It Fits
You have data in three or more tools, spend hours copying into spreadsheets, and need one dependable view with metrics everyone agrees on.
✕When It Doesn't
You need real-time algorithmic trading data feeds or enterprise data lakes for petabyte-scale unorganized files.
Use Cases
Business Use Cases We Serve
Weekly reporting scramble
Fridays spent pulling CSVs and pasting into sheets — automated into a live dashboard with zero manual copying.
Numbers that disagree
Marketing says one number, finance says another — unified data models where metrics have one clear source.
Slow, broken dashboards
Legacy BI reports taking minutes to load — rebuilt with pre-aggregated tables for sub-second response.
Gallery
What Typical Deliverables Look Like
Sample deliverables from a typical engagement — yours follow the same shape, scoped to your business.
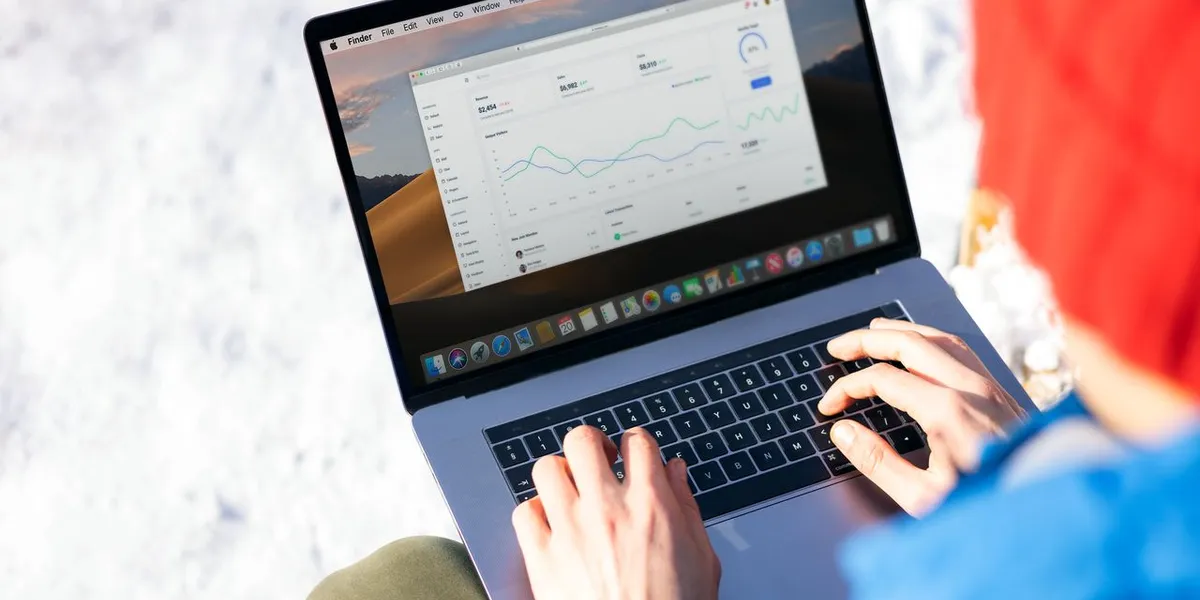
Visual 1
Automated ingestion
Pipelines pulling clean data from all tools daily with zero manual work.
Visual 2
Dimensional models
Star-schema models in dbt where metrics have one verified formula.
Visual 3
Executive dashboard
Sub-second dashboards showing the numbers that drive real decisions.
Timeline
How Long Does dashboards project Take?
First dashboard typically 2–4 weeks after data access and scope agreement. The same four delivery stages run every engagement — you approve progress at each gate before the next begins.
Stage 1
Metric inventory
Map every tool, table and metric with stakeholders — agreeing on exact formulas before building.
Stage 2
Pipeline & warehouse
Automated extraction into clean staging tables, modeled with dbt for reliable daily refreshes.
Stage 3
Dashboard & testing
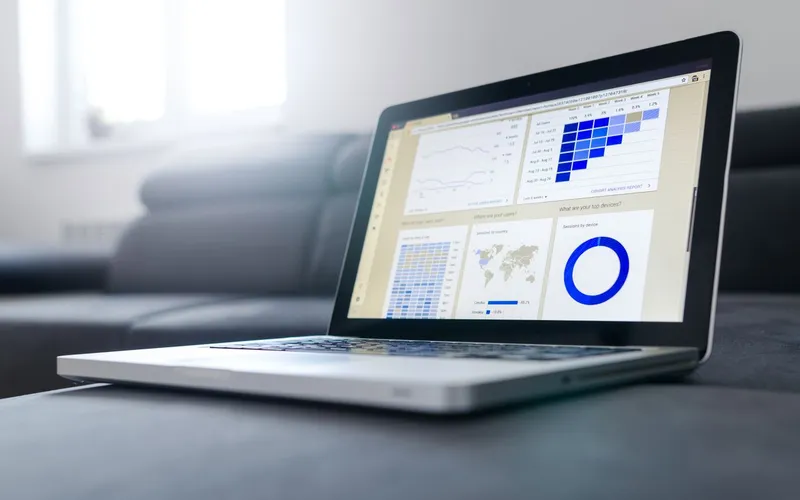
Executive and operational dashboards built with pre-aggregations, tested against source records.
Stage 4
Handover & guide
Data dictionary, lineage docs and team walkthrough — your team owns every query and dashboard.
Pricing
What Drives the Cost of dashboards project?
- 1
Number and cleanliness of source tools and APIs
- 2
Historical data volume and backfill requirements
- 3
Dashboard complexity and custom metric modeling
Pricing shape: Fixed-price project per dashboard suite; ongoing pipeline monitoring optional.
Indicative ranges live on the pricing page — your fixed quote arrives with the discovery scope.
Process
Delivery Stack and Pricing
Stages shown above — here is what they run on and how they are priced.
Stack & Tools
SnowflakeGoogle BigQuerydbt (data build tool)Apache Airflow / DagsterPostgreSQLApache KafkaMetabaseApache SupersetClickHousePython / PandasTableauLooker
Pricing Shape
Fixed-price project per dashboard suite; ongoing pipeline monitoring optional.
Due Diligence
Technical Due Diligence FAQs
How much does dashboards project cost?
After a short paid discovery (typically 1–3 weeks) you receive a fixed price with milestones. Fixed-price project per dashboard suite; ongoing pipeline monitoring optional. Discovery is credited toward the build if you proceed.
What is the difference between an ETL and an ELT data pipeline architecture?
In traditional ETL (Extract, Transform, Load), data is transformed on an intermediate processing server before being loaded into the destination database. This architecture is rigid, slow to adapt, and discards raw data during transformation. In modern ELT (Extract, Load, Transform), raw data is extracted from source systems and loaded directly into a cloud data warehouse (such as Snowflake or BigQuery) in its original format. Transformations are then executed directly inside the warehouse using SQL via dbt (data build tool). ELT preserves complete historical raw data, allows analysts to modify transformation logic retroactively without re-extracting data from source APIs, and leverages the massive parallel processing power of modern cloud warehouses for lightning-fast execution.
How do you ensure that analytical queries never slow down our live production web application database?
We completely isolate analytical reporting workloads from production transactional systems. We never connect business intelligence dashboards directly to your primary production application database. Instead, we implement Change Data Capture (CDC) or read-only replica extraction that streams data changes asynchronously into a separate cloud data warehouse. In addition, analytical queries execute against dedicated compute clusters designed specifically for columnar OLAP queries, ensuring that heavy end-of-month reporting or complex multi-year cohort queries consume zero CPU or memory resources on your customer-facing production servers.
What is dbt (data build tool), and why is it essential for modern enterprise data teams?
dbt (data build tool) is the industry standard framework for authoring data transformation pipelines using version-controlled SQL and Jinja. Instead of maintaining messy, uncoordinated SQL scripts scattered across different tools, dbt allows data engineers to write modular, reusable transformation models that compile into clean database tables and views. dbt automatically manages table dependencies, builds comprehensive visual data lineage graphs, handles incremental data processing, and executes automated data quality tests on every run. By bringing software engineering best practices—such as Git version control, automated CI/CD testing, and documentation—to data analytics, dbt ensures your data pipelines are robust, transparent, and easily maintainable.
How do you handle sensitive customer personal information (PII) within the analytical warehouse?
We implement strict data governance and privacy engineering controls following HIPAA, GDPR, and SOC 2 requirements. During the ELT ingestion phase, sensitive personal identifiers—such as Social Security numbers, credit card tokens, and raw passwords—are either stripped entirely or hashed using cryptographic one-way hashing algorithms (such as SHA-256 with secret salt). For fields requiring operational analysis (such as customer email domains or geographic postal codes), we implement column-level encryption and dynamic data masking. Using role-based access control (RBAC), only authorized personnel with verified operational clearance can view unmasked sensitive attributes, while general business users interact exclusively with anonymized, de-identified analytical marts.
Which cloud data warehouse do you recommend: Snowflake, Google BigQuery, or ClickHouse?
The optimal warehouse depends on your existing cloud infrastructure, query patterns, and data volume. Google BigQuery is extraordinary for organizations already hosted on Google Cloud or utilizing Google marketing platforms, offering true serverless auto-scaling with zero infrastructure maintenance. Snowflake is ideal for cross-cloud enterprise environments requiring sophisticated data sharing, dynamic workload isolation between teams, and fine-grained credit management. ClickHouse is unmatched for ultra-high-velocity real-time event streaming, IoT telemetry, and web analytics requiring sub-second response times across billions of rows at a fraction of traditional cloud compute costs. During our discovery phase, we evaluate your technical topology and data velocity to recommend the most cost-effective and performant warehouse for your specific needs.
How do you prevent 'dashboard sprawl' where companies end up with hundreds of abandoned reports?
Dashboard sprawl occurs when ad-hoc reports are created without governance or clear operational owners, leading to confusion and stale numbers. We prevent this through disciplined semantic modeling and strict dashboard lifecycle governance. We design an organized dashboard hierarchy: an Executive Overview tier (containing the top 5-7 core business KPIs), Departmental Tactical views (Marketing, Sales, Operations, Finance), and specialized Deep-Dive Explorer views. Every dashboard is assigned a named business owner, explicit update cadence, and defined decision context. We also implement access telemetry to identify and retire unused reports, maintaining a lean, authoritative reporting suite that leadership actively relies on daily.
What happens when an upstream SaaS tool changes its API or data structure unexpectedly?
Upstream API schema drift is one of the most common causes of silent data pipeline failure. We protect against this by engineering resilient pipeline architecture with automated schema evolution and data validation gates. Our ingestion connectors leverage schema drift handling that captures newly added JSON fields dynamically without crashing pipelines. Before data is promoted to downstream executive reporting marts, automated Great Expectations test suites validate column names, data types, and value bounds. If an upstream vendor alters a field or introduces unexpected null values, the flawed batch is quarantined in an error table, an alert is immediately dispatched to your engineering Slack channel, and downstream dashboards continue serving verified historical data rather than displaying corrupted or blank calculations.
Can our business intelligence dashboards be embedded directly into our customer-facing web application?
Yes. We frequently architect customer-facing embedded analytics for B2B SaaS platforms. Using tools like Metabase Embedded, Apache Superset, or custom Cube.js API backends with React charting libraries (such as Tremor or Recharts), we embed white-labeled interactive dashboards directly into your web application. Multi-tenant security is enforced cryptographically using signed JSON Web Tokens (JWT) and row-level security (RLS) filters, ensuring that each enterprise customer can view and export only their own proprietary organizational data with sub-second page load times.
Who owns the data warehouse code, transformation logic, and dashboard configurations?
Your organization maintains one hundred percent exclusive ownership of all source code, dbt models, SQL transformation queries, pipeline DAGs, and dashboard definitions from day one. Everything is developed inside your corporate GitHub or GitLab repositories and provisioned directly within your corporate cloud accounts. We do not utilize proprietary agency data middleware or charge recurring software license fees. Upon completion, we provide comprehensive data dictionaries, metric calculation documentation, and recorded training walkthroughs so your internal team can independently manage and extend the platform without external reliance.
What ongoing maintenance and pipeline monitoring options do you provide after deployment?
Following production deployment, we provide structured ongoing support agreements covering continuous pipeline monitoring, warehouse compute cost optimization, and SLA management. We configure automated alerting through Slack, PagerDuty, or email to notify our engineers immediately of any pipeline delays, sync failures, or data quality anomalies. We also offer monthly sprint hours dedicated to building new data source integrations, optimizing warehouse clustering keys to reduce query spend, and authoring new executive reporting models as your business expands.
How long does it take to start?
Discovery starts within days of agreement. Builds run in weekly sprints with a demo every week.
Who owns the work?
You do, under a signed agreement — code, docs and accounts are handed over at the end.
Content last reviewed September 2026.
Straight Talk
Mistakes We Prevent & How We Compare
Common mistakes we prevent
Building dashboards before agreeing on metric formulas — inventory first
Querying live production databases for heavy reporting — warehouse always
No data quality alerts — pipeline testing from day one
Us vs the usual alternative
Data pipeline
AnyPlace: Automated ELT with quality checks
Typical alternative: Manual CSV downloads weekly
Speed
AnyPlace: Sub-second queries via pre-aggregations
Typical alternative: Slow reports that time out
Ownership
AnyPlace: All code in your Git repo
Typical alternative: Locked inside a proprietary SaaS
Before
The starting point we usually find
Fridays spent pasting CSVs into fragile spreadsheets; meetings derailed arguing whose numbers are correct.
After
Where this service leaves you
One fast, trusted dashboard suite refreshing daily — everyone agrees on the numbers, and decisions happen on facts.
Worth knowing: Gartner research indicates that poor data quality costs organizations an average of $12.9 million annually — reliable pipelines protect business value. Source: Gartner Research · Verified September 2026
Related Services
Pairs Well With
Custom Software Development
Web platforms, business tools and APIs — planned in milestones, built in weekly sprints, handed over with docs and tests.
View service→
Cloud Setup & DevOps
Cloud hosting setup, CI/CD pipelines and cost hygiene on AWS, Azure or GCP — with runbooks your team can follow.
View service→
AI-Assisted Features & Automation
Practical AI pilots — search, summaries, triage and workflow helpers — scoped narrowly and evaluated before scaling.
View service→
TELL US ABOUT YOUR PROJECT
Tell Us What to Build, Fix or Modernize
Send a short brief. We reply within 12 hours with clarifying questions and a discovery quote — no retainers, no spam.
What Happens Next
Request a Discovery Quote
Share your goals and timeline. NDA signed first if needed.
12-hour response